❯ cat projects/media-archive.md
Searchable Media Archive
Client · James Waring Archive · 2026
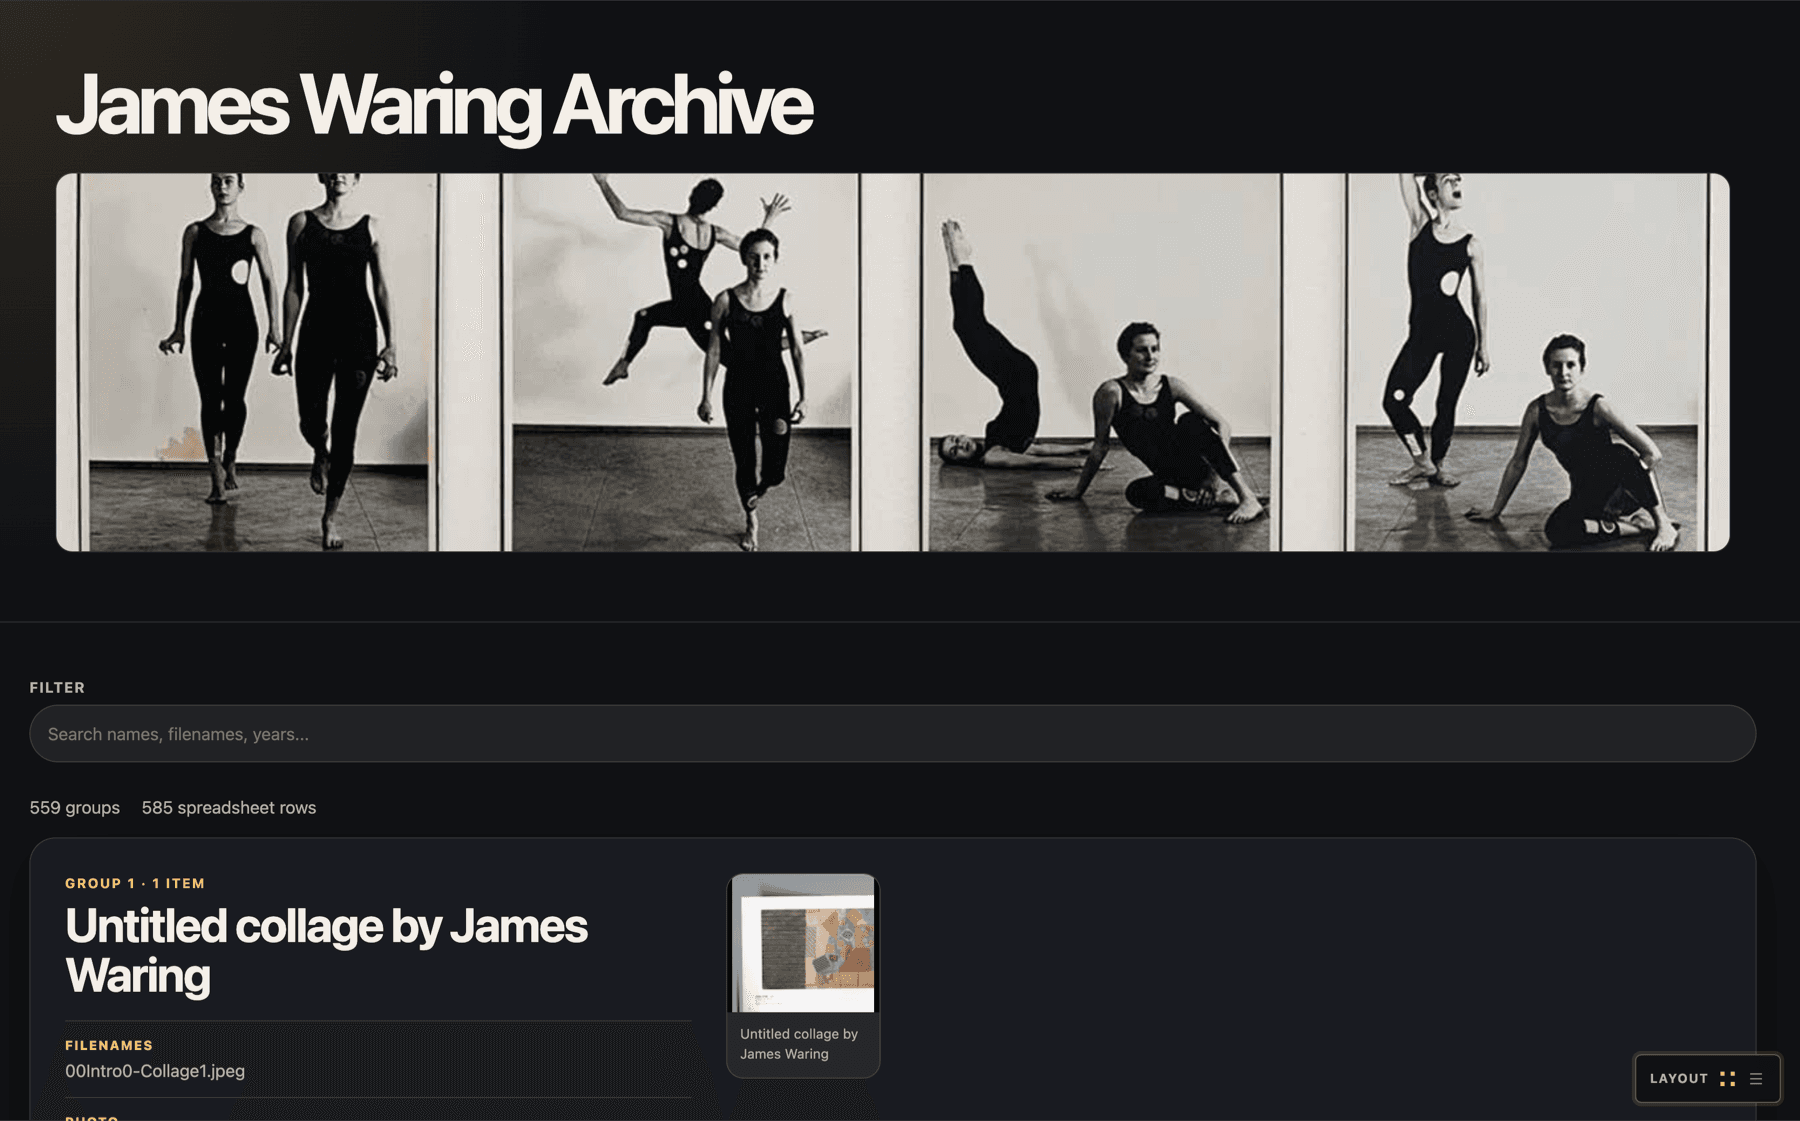
A browsable web catalog of the James Waring Archive: photographs, collages and ephemera from the choreographer's work, each scan paired with clean, standardized metadata behind one search box.
- my part
- Design & development, LLM-assisted data cleaning, manual audit.
- credits
- Julia Vvedenskaya (design & development), Vincent Naples (data pipeline)
- stack
- LLMs, Google Sheets, Google Drive, Data pipelines
- links
- Archive viewer
## context
The James Waring Archive documents the work of choreographer James Waring in photographs, collages and ephemera, held at the Charles Deering McCormick Library of Special Collections at Northwestern University. It needed a browsable web catalog.
## challenge
The whole catalog arrived as one Google Doc rather than a spreadsheet: wrong indexes, no consistent schema, and fields that drifted from record to record. Images lived separately in Google Drive. Before anything could be displayed, the archive had to become structured data.
## what i built
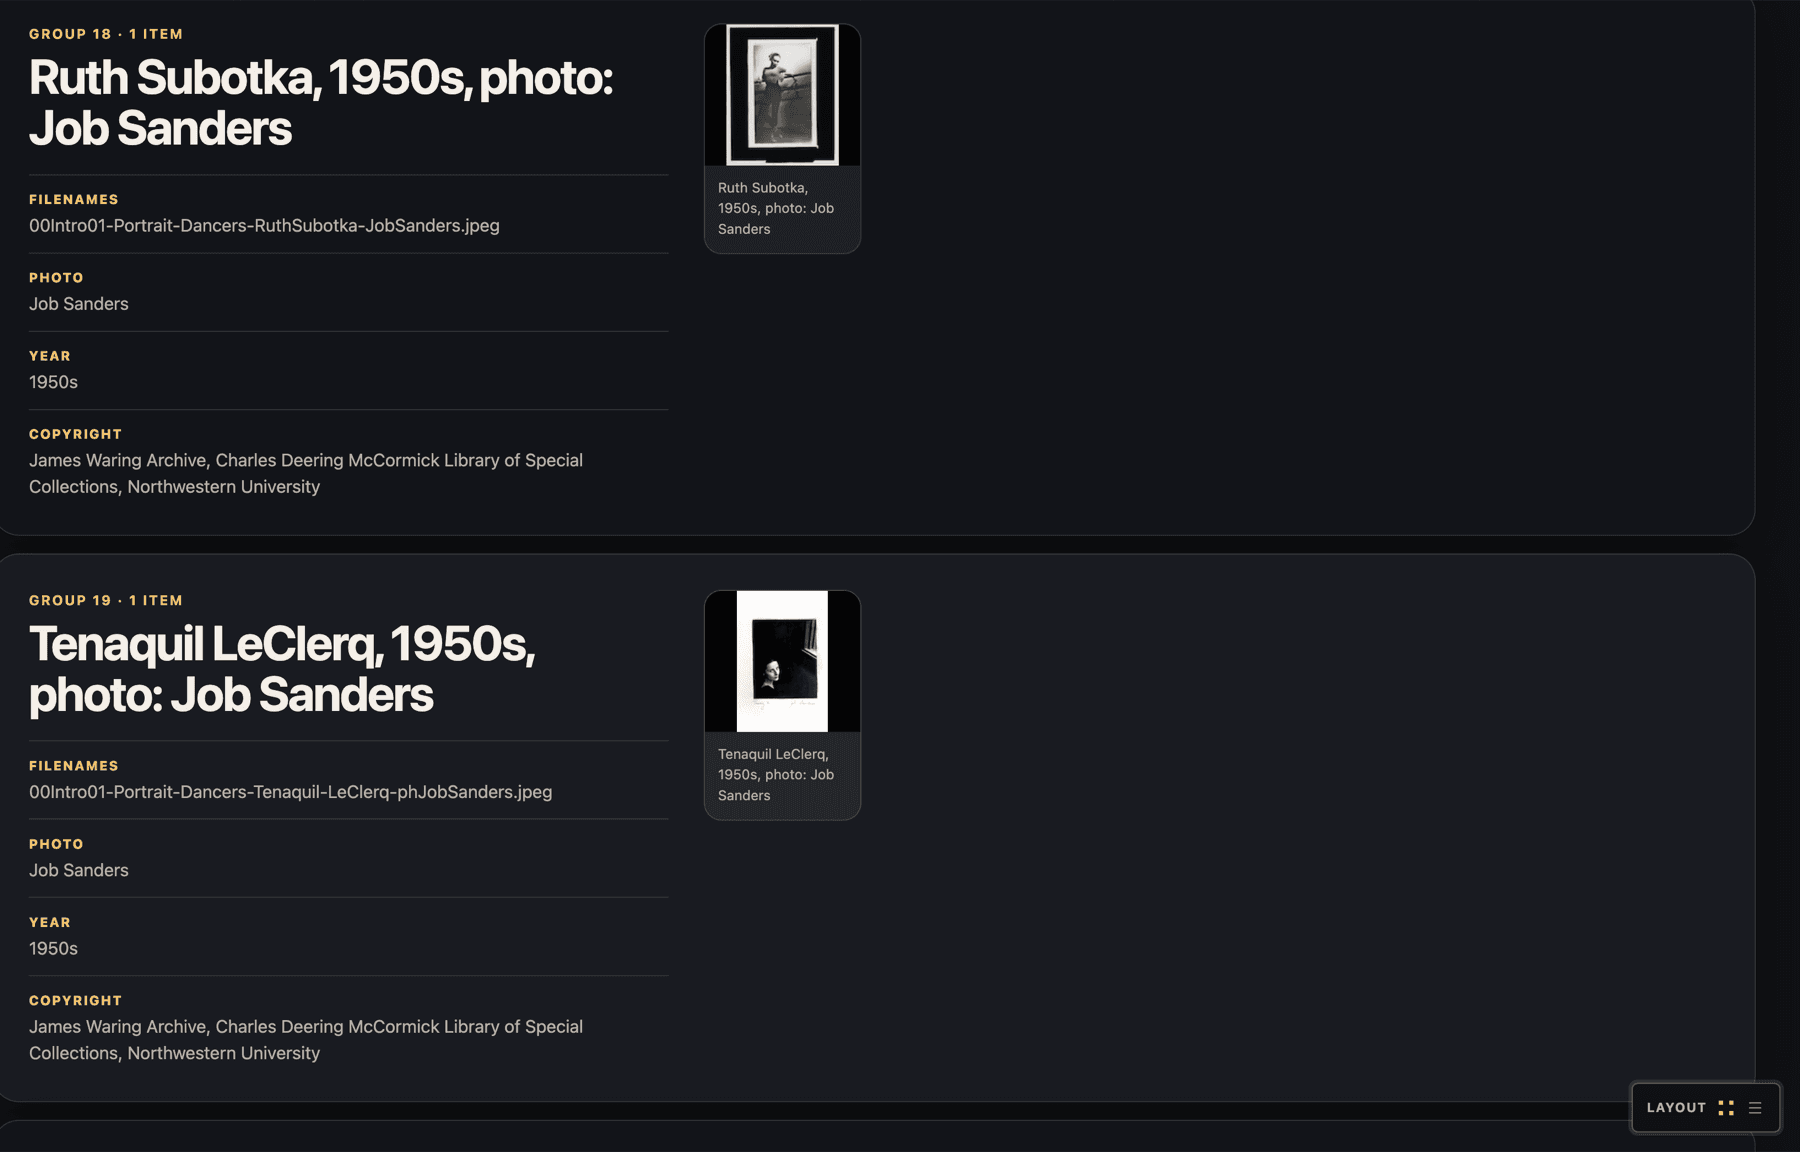
A data pipeline that turned the document into structured records, and a viewer that pairs each scanned image with standardized metadata (title, photographer, year, copyright) behind one search box covering names, filenames and years.
## approach & trade-offs
An LLM parsed the freeform document, inferred a consistent schema, reconciled the broken indexes and mapped every entry into the same shape. The result went into Google Sheets, where I audited it row by row against the source before using that sheet as the viewer's data layer. The model did the bulk work; the manual audit made it trustworthy.
## outcome
585 clean records grouped into 559 catalog entries, searchable and image-rich.
--
cd .. | next: Community Network Map